Posts

Showing posts with the label data extraction

Web Scraping using BeautifulSoup library.

Image
  What is it a Beautifulsoup library? Beautiful Soup  is a Python library for pulling data out of HTML and XML files. It works with your favorite parser to provide idiomatic ways of navigating, searching, and modifying the parse tree. To install Beautifulsoup: pip install bs4 What is the requests library? The  library is the de facto standard for making HTTP requests in Python. It abstracts the complexities of making requests behind a beautiful, simple API so that you can focus on interacting with services and consuming data in your application. To install requests: pip install requests What is the html5lib library? html5lib is a pure python library for parsing HTML. It is designed to conform to the WHATWG HTML specification, as is implemented by all major web browsers.    To install html5lib: pip install html5lib Steps: Installing the required third-party libraries. Accessing the HTML content from the webpage. Parsing the HTML content. Searching and navig...

Web scrapping/web data extraction from website using python.

Image
Scrapping table data from website Web Scrapping: Web scrapping is technique to fetch data from websites. It is known as web data extraction.   We can do web scrapping using many ways. There are many ways to get web table data using urllib and BeautifulSoup, but its lengthy, complex and also time-consuming process.   To avoid these disadvantages, we use the pandas library. We can do same task using pandas library.                   read_html(): read_html() is the method in pandas library is a web scraping tool that extracts all the tables on a website by just giving the required URL as a parameter. Read HTML tables into a list of data frame objects.             Syntax: pandas.read_html(url, other parameters)                    Important  Parameters: match: This parameter is used for extracting the targeting table.   ...

Data extraction from PDF files using python.

Image
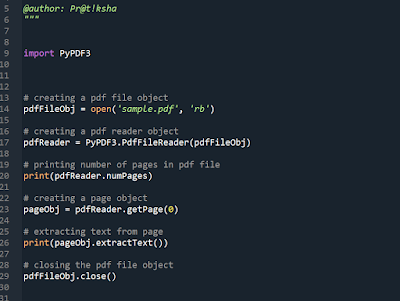
 Data Extraction from PDF:  The basic concept of extract text from PDF files means to get important (What you want from PDF) data from PDF files. There are available lots of libraries for text extraction from PDF files. PyPDF invoice2data textract pdfMiner pdf plumber tabula (for extract tabular data) Let’s start with PyPDF : PyPDF is capable of Splitting documents page by page. Merging documents page by page. Cropping pages. Extracting document information. Encrypting and decrypting PDF files. To install PyPDF type the below command in the terminal: pip install PyPDF2 (For python2) pip install PyPDF3 (For python3) 2.  Tabula:  tabula-py is a simple Python wrapper of  tabula-java , which can read tables in a PDF.      Tabula is one of the useful packages which not only allows you to scrape tables from PDF files    but also convert a PDF file directly into a CSV file.           To install tabula library: ...