Data extraction from PDF files using python.
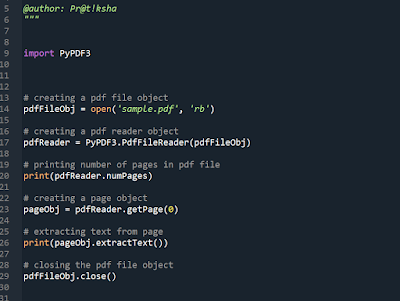
Data Extraction from PDF: The basic concept of extract text from PDF files means to get important (What you want from PDF) data from PDF files. There are available lots of libraries for text extraction from PDF files. PyPDF invoice2data textract pdfMiner pdf plumber tabula (for extract tabular data) Let’s start with PyPDF : PyPDF is capable of Splitting documents page by page. Merging documents page by page. Cropping pages. Extracting document information. Encrypting and decrypting PDF files. To install PyPDF type the below command in the terminal: pip install PyPDF2 (For python2) pip install PyPDF3 (For python3) 2. Tabula: tabula-py is a simple Python wrapper of tabula-java , which can read tables in a PDF. Tabula is one of the useful packages which not only allows you to scrape tables from PDF files but also convert a PDF file directly into a CSV file. To install tabula library: ...